Scalexa
November 5, 2026

Daily Insights: Tech & Review

Scalexa Curation
6 Articles
Article 1

The Best AI Coding Assistants of 2026: From Cursor to Google Antigravity

The Best AI Coding Assistants of 2026: From Cursor to Google Antigravity

AI-First Editors vs. Traditional PluginsIn the fast-evolving world of development, AI News in 2026 is centered on the dominance of AI-first editors. While plugins like GitHub Copilot remain popular for boilerplate generation, tools like Cursor and Google Antigravity have redefined the workflow by maintaining awareness of the entire codebase rather than just a single file. At Scalexa, we have integrated these "Agentic Editors" into our full-stack pipeline, allowing our developers to describe complex refactors in natural language that the AI then applies across dozens of files simultaneously. These tools function as autonomous partners that operate across the editor, terminal,...
Article 2

The 2026 React Stack: Scaling AI-Native Web Apps with Scalexa

The 2026 React Stack: Scaling AI-Native Web Apps with Scalexa

AI-Native Frontend EngineeringAs AI News reports, the "React Stack for 2026" has evolved to place AI at the very core of the application logic. At Scalexa, we are building web apps that are no longer just rule-based systems but autonomous, goal-driven structures. By leveraging meta-frameworks like Next.js 16 and the latest React Compiler, we ensure that your UI is dynamically generated based on real-time user behavior and environmental data. This "Predictive UX" anticipates user needs, reducing friction and significantly improving Core Web Vitals. Scalexa’s expertise in "Vibe Coding"—where outcomes are described in natural language...

Article 3

NVIDIA Nemotron-3-Super vs. Llama 3.3: Choosing the Right Engine for Your Workflows

NVIDIA Nemotron-3-Super vs. Llama 3.3: Choosing the Right Engine for Your Workflows

The Battle of the Open WeightsIn this week’s AI News, the debate centers on NVIDIA’s Nemotron-3-Super versus Meta’s Llama 3.3. While Llama remains a versatile powerhouse, Nemotron-3-Super is built for "Throughput Excellence." At Scalexa, we have benchmarked these models and found that Nemotron’s hybrid Mamba-Transformer architecture delivers up to 7x faster inference for long reasoning sequences. For a high-volume brand, this isn''t just about being fast; it''s about the "Psychology of Momentum." When your team doesn''t have to wait for an AI to "think," their creative flow remains unbroken. Scalexa specializes in matching...

Article 4

The Backbone of Memory: A Deep Dive into Vector Databases and RAG Architecture

The Backbone of Memory: A Deep Dive into Vector Databases and RAG Architecture

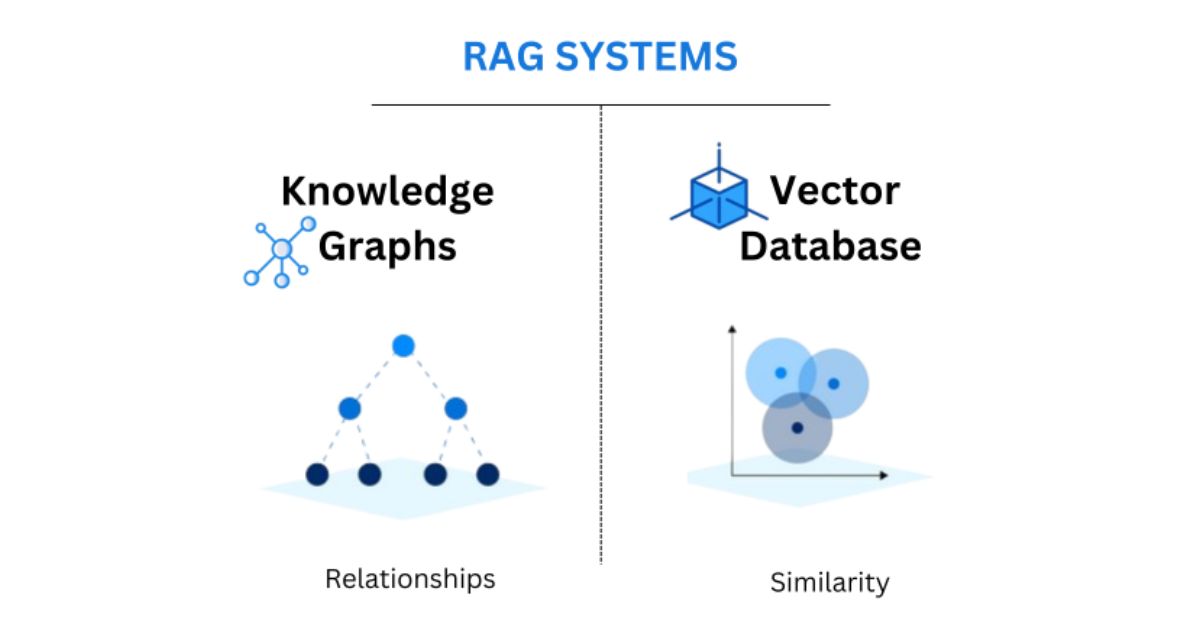
Solving the AI "Hallucination" ProblemOne of the most frequent topics in AI News at Scalexa is the refinement of Retrieval-Augmented Generation (RAG). While early AI models often suffered from "hallucinations"—confidently stating false information—modern RAG architectures solve this by connecting the LLM to a high-speed Vector Database like Pinecone, Milvus, or Weaviate. This allows the AI to "look up" facts in your company''s private documentation before generating an answer. For a technical agency like Scalexa, this means building support bots and internal search engines that are 100% accurate because they are grounded in real-time, verified data. The...

Article 5

LFM2 vs. Llama 3.3: The Battle for the Pareto Frontier

LFM2 vs. Llama 3.3: The Battle for the Pareto Frontier

Choosing Efficiency Over HypeIn this week’s AI News, the debate centers on the "Pareto Frontier" of AI—the perfect balance between quality and speed. While Llama 3.3 is a powerhouse, the LFM2 series dominates in prefill and decode throughput, especially on non-GPU hardware. At Scalexa, we’ve benchmarked these models and found that for math-heavy and long-context tasks, LFM2’s hybrid LIV (Linear Input-dependent Variable) operators provide a significant edge. Psychologically, this "Constant-Time" inference reduces the anxiety of scaling; your costs stay predictable even as your data grows. Scalexa helps you navigate these benchmarks to choose the engine that actually...

Article 6

The New AI Economy: Solving the Verification Crisis and the Junior Loop

The New AI Economy: Solving the Verification Crisis and the Junior Loop

The Economics of VerificationWe have reached a profound economic inflection point: the cost of executing a cognitive task is approaching zero, but the cost of verifying that the task was done correctly is skyrocketing. This "Verification Crisis" is the new bottleneck for tech-centric businesses. While an LLM can generate 10,000 lines of code or a 50-page legal audit in seconds, a senior human expert must still spend hours ensuring the output is factually sound and legally compliant. This shift is giving rise to "Liability-as-a-Service" models, where future software providers won''t just sell tools, but will legally underwrite...

Share This Digest

You've reached the end!

Check back tomorrow for a fresh automated delivery of curated technology and automation articles.

View All Newsletters

Explore Topics

Discover articles across all our categories and tags

Available Topics

Popular Tags

Start Project
WhatsApp
Read Next
Explore